Why AI Engines Cite Reddit So Often
Why do AI engines cite Reddit? Follow the licensing deals, retrieval-friendly Q&A format, live data access, and conflicting citation studies.
On this page
AI engines cite Reddit often because its question-and-answer threads contain fresh, first-hand language that is easy to retrieve, while official data partnerships give Google and OpenAI reliable structured access. That explains the recurring pattern, not every individual citation: rates vary sharply by engine, query set, and week.
This analysis is for marketers, researchers, and product teams that need to interpret Reddit citation claims. It explains access, retrieval fit, experience signals, stability, and measurement disagreements; it is not a tactical guide to posting on Reddit or a claim that licensing causes every citation.
Ask ChatGPT for a recommendation on almost anything — a mattress, a CRM, a fix for a weird noise your car is making — and there's a decent chance one of the sources cited is a Reddit thread. Google AI Overviews surfaces Reddit too, although the rate changes with the study and sample. This isn't only the algorithm "discovering" that Reddit happens to be good. Reddit negotiated official data access with Google and OpenAI, tightened crawler and commercial-use controls, and later sued companies over alleged unlicensed use. I run FixAEO, where we track how often brands get cited across ChatGPT, Claude, Gemini, Perplexity, Grok, DeepSeek, Copilot, and Google AI Overviews, and Reddit is the single domain that generates the most "wait, why does that keep showing up" questions from people using the product. So here's the actual story: the money behind it, what the citation data really shows, and the parts of the narrative that don't hold together as cleanly as most write-ups suggest.
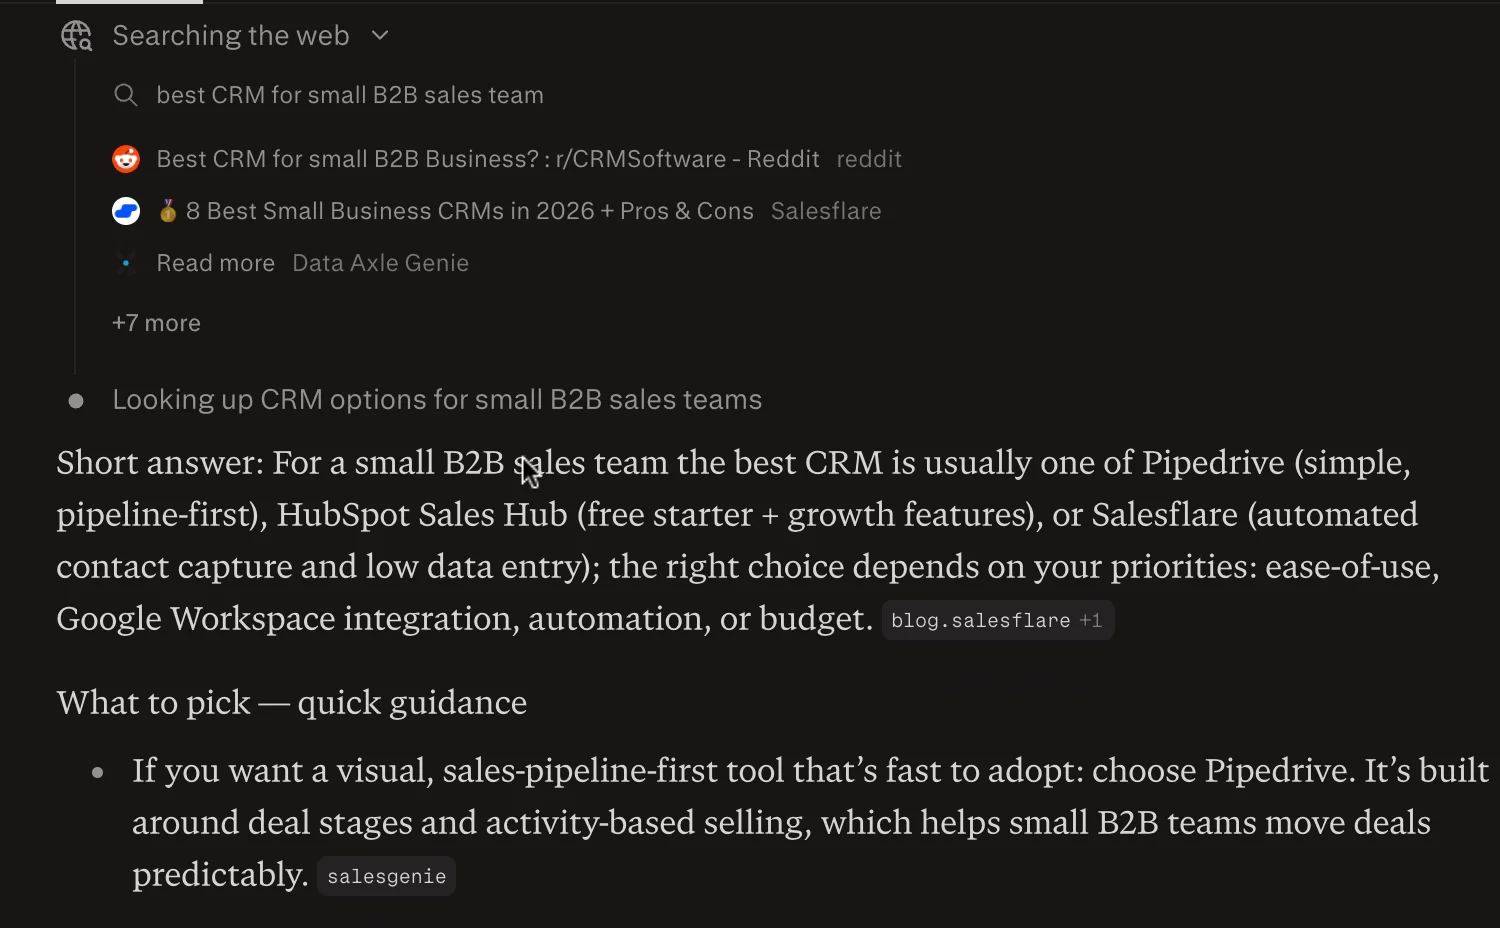
This is the visible retrieval layer: Reddit is one source among several. It does not prove that licensing alone caused the citation or that the Reddit result controlled the answer.
The short answer: money, access, and what people actually want
Three things are happening at once here, and they get conflated constantly.
First, Reddit sold structured, real-time API access to Google and OpenAI and built a real revenue line around it. Second, Reddit tightened crawler, API, and commercial-use controls, giving licensed partners a more reliable route than companies relying on ordinary crawling. Third, independent of the money, forums satisfy something search was missing: people asking "has anyone actually tried this" and getting a first-hand answer instead of a listicle written to rank. Google's own former Search Liaison, Danny Sullivan, said as much — he described people "craving" authentic, experience-based content, partly in reaction to "a lot of terrible content out there... generated through content marketing" (ppc.land).
All three of those are true at once. None of them alone explains the whole picture — and, as you'll see in the data section below, even with the money and access sorted out, different research firms still can't agree on how often Reddit actually gets cited.
The licensing deals that changed everything
Google's $60 million-a-year deal
In February 2024, Reuters reported that Google had agreed to pay Reddit roughly $60 million a year to license Reddit's data for AI training and search. The timing was pointed — the report landed one day before Reddit's IPO filing became public (MediaPost, citing Reuters). That filing itself disclosed data-licensing arrangements worth $203.0 million in aggregate contract value over two-to-three-year terms, with at least $66.4 million expected to be recognized in 2024 alone (TechCrunch). Licensing its own users' posts turned into a real line item on Reddit's balance sheet, right as it needed one for the public markets.
One historical wrinkle is worth knowing: OpenAI CEO Sam Altman entered Reddit's 2024 IPO as a major shareholder after investing in the company in 2014 (Reddit's 2024 S-1). He recused himself from OpenAI's decision to partner with Reddit. This is governance context, not evidence that his stake caused the partnership or any citation outcome.
OpenAI's deal, and the estimate nobody's confirmed
Three months after the Google deal broke, OpenAI announced its own partnership on May 16, 2024: access to Reddit's Data API, Reddit content surfaced inside ChatGPT and other OpenAI products, and OpenAI signing on as a Reddit advertising partner too (TechCrunch). Neither company disclosed the dollar figure.
Search Engine Land later put a number on it — roughly $70 million a year — but they're upfront that it's their own back-of-envelope math, not an official figure: they took Reddit's disclosure that AI licensing is about 10% of its roughly $1.3 billion 2024 revenue, then subtracted Google's confirmed $60 million (Search Engine Land). Treat that $70M as an estimate, not a contract term, every time you see it repeated elsewhere.
Reddit controls the door — but robots.txt is no longer the whole story
Selling access to two AI giants only works if Reddit can control everyone else's bulk use. In July 2024, reporting showed Reddit's robots.txt blocking major crawlers while Google retained access under its paid deal (Waxy.org / 9to5Google). Bing, DuckDuckGo, Mojeek, and Qwant temporarily lost the ability to index or display Reddit content, and Reddit said it wanted commitments that crawlers would not use the data for unauthorized AI training.
That 2024 snapshot is still repeated as if the file never changed. It did. Reddit's current robots.txt uses a broad User-agent: * rule that allows the site while excluding specific formats, search paths, APIs, GraphQL, and other endpoints. That does not grant an AI company a data license, and it does not erase Reddit's API terms or later enforcement. It means the defensible 2026 explanation is broader: Reddit controls access through crawler directives, API terms, negotiated licenses, technical restrictions, and lawsuits. "Only Google can crawl Reddit" is no longer an accurate description of the live file.
| Factor | What the evidence supports | What it does not prove |
|---|---|---|
| Google and OpenAI deals | Both companies receive real-time, structured Reddit Data API access. | That every Reddit citation comes from the paid API. |
| Thread structure | Questions, replies, timestamps, and vote signals are retrieval-friendly. | That upvotes alone determine what gets cited. |
| First-hand experience | Recommendation prompts often benefit from user accounts and trade-offs. | That every Reddit answer is accurate or authentic. |
| Robots and API controls | Reddit can limit routes, formats, and bulk access and enforce separate terms. | That today's robots.txt permanently blocks every non-paying crawler. |
The ARES model: four conditions behind a durable Reddit citation
The evidence is easiest to reason about through ARES, a four-condition model I use to separate access from citation outcomes:
- Access — the engine can retrieve the thread through crawling, indexing, or licensed data access.
- Retrieval fit — the thread contains a self-contained passage that matches the prompt closely enough to reuse.
- Experience evidence — the passage supplies a situation, result, trade-off, or first-person detail that a generic brand page lacks.
- Stability — the URL remains accessible and keeps appearing across repeated checks rather than one volatile snapshot.
Access is necessary but not sufficient. A commercial data deal can improve availability, but it cannot make a vague comment answer a prompt; likewise, an excellent comment cannot be cited if the engine cannot retrieve or retain the page. ARES explains why "Reddit has a licensing deal" and "Reddit has useful answers" are complementary explanations rather than competing ones.
What the data actually shows (and why it doesn't agree with itself)
Here's where I want to be careful, because most posts on this topic quote one big Reddit-citation-share number as if it's settled fact. It isn't. Different research firms sample different queries, different date windows, and different definitions of "citation," and they come back with numbers that flatly contradict each other. Read each one as a snapshot from one angle, not as "the" Reddit citation rate.
Ahrefs: Reddit doesn't crack the top 10 on ChatGPT or Perplexity
Ahrefs' Brand Radar analyzed roughly 76.7 million Google AI Overviews, about 957,000 ChatGPT prompts, and around 953,500 Perplexity prompts in June 2025. It found Reddit held a 7.4% citation share in Google AI Overviews — but didn't rank in the top 10 most-cited domains for either ChatGPT or Perplexity. Wikipedia led all three platforms in that sample: 16.3% on ChatGPT, 12.5% on Perplexity, and 8.4% on AI Overviews (Ahrefs).
Semrush: Reddit's ChatGPT citations collapsed from 60% to 10% in six weeks
Semrush tracked 230,000 prompts across ChatGPT Search, Google AI Mode, and Perplexity over 13 weeks (July 14 to October 12, 2025), covering more than 100 million total citations. Reddit's share of ChatGPT citations swung from roughly 60% of responses in early August 2025 down to about 10% by mid-September — a sharp, ChatGPT-specific move the researchers attributed to a deliberate algorithm change, not a glitch. Google AI Mode and Perplexity stayed comparatively stable over the same window (Semrush).
That's arguably the most important number in this whole piece: Reddit's citation rate isn't just measured differently by different vendors, it's genuinely volatile inside one vendor's own tracker. Any claim you read that "ChatGPT cites Reddit X% of the time" is probably already stale by the time you read it.
Semrush again: Reddit as the #1 cited domain on Perplexity
A separate Semrush study, refreshed in October 2025, looked at 248,000 Reddit URLs cited across 217,000 prompts and ranked Reddit as the #1 cited domain in its Perplexity sample, #2 on SearchGPT at 12.6% of responses, and #3 on Google AI Mode at 9%. Q&A-thread posts alone made up more than half of all Reddit citations. And 80% of the cited Reddit posts had fewer than 20 upvotes — meaning upvote count doesn't appear to be what gets a post cited (Semrush).
Notice this contradicts Ahrefs' finding that Reddit missed Perplexity's top 10 entirely, from a study run around the same period. Different sample, different query set, different answer. Both can be honest reflections of what each vendor actually measured.
SE Ranking and Advanced Web Ranking: stability matters, but samples still matter
SE Ranking's July 2026 study followed 482 Reddit posts across 135 subreddits through six checks over three months and recorded 7,307 citations across Google AI Overviews, AI Mode, ChatGPT, and Gemini. Only 42 posts survived all six checks, but that 9% of the sample generated roughly 48% of all recorded citations. Those durable posts averaged 83.4 citations each, versus 1.6 for posts that appeared once — a 52x gap. This does not prove that age or persistence causes citation, but it shows why a one-day visibility check can badly misrepresent which Reddit threads keep getting retrieved (SE Ranking).
Advanced Web Ranking ran a smaller, more hands-on study — 40 SEO queries against Google AI Overviews and Bing Copilot Search in late July 2026 — and found Reddit accounted for 43 of 201 citations, about 21%, across the 12 fully-expanded AI Overview answers they could analyze in detail. Reddit, YouTube, and LinkedIn together made up 59% of all citations in that sample (Advanced Web Ranking). Forty queries is a small sample, so treat this one as directional, not a market-wide statistic.
Profound: Reddit leads Google AI Overviews and Perplexity in a 680M-citation dataset
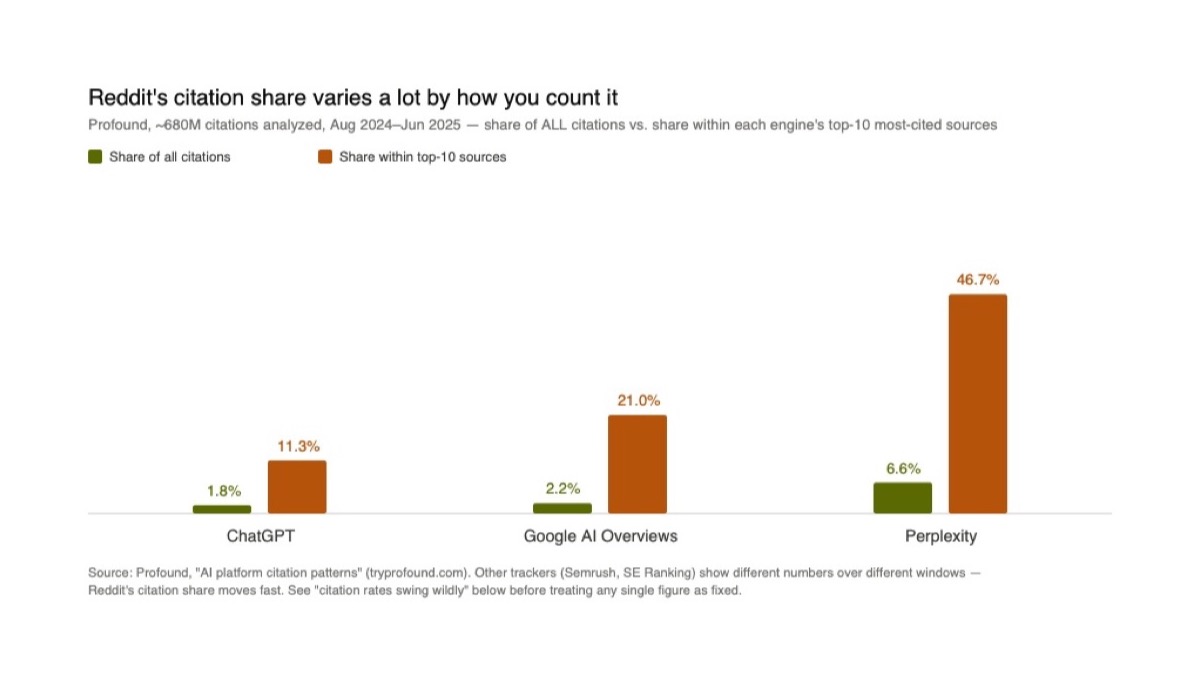
Profound's primary report covers roughly 680 million citations from August 2024 through June 2025. It separates overall citation volume from share within each engine's top 10 sources: Reddit accounted for 1.8% of ChatGPT citations, 2.2% of Google AI Overviews citations, and 6.6% of Perplexity citations overall; within each platform's top 10 sources, those shares were 11.3%, 21.0%, and 46.7% respectively (Profound). That denominator distinction explains why two honest summaries of the same study can appear to disagree by more than 7x.
FixAEO source audit: six studies, six different measurement shapes
I normalized the research above into the fields most summaries omit: sample, window, unit of analysis, reported Reddit result, and comparability limit.
| Research output | Sample and window | What it measured | Reddit signal | Why it is not directly comparable |
|---|---|---|---|---|
| Ahrefs Brand Radar | 76.7M AI Overviews, ~957K ChatGPT prompts, ~953.5K Perplexity prompts; June 2025 | Domain citation share and top-domain rank | 7.4% in AI Overviews; outside the top 10 for ChatGPT and Perplexity | One-month cross-platform snapshot with Ahrefs' prompt set |
| Semrush longitudinal tracker | 230K prompts and 100M+ citations; 13 weeks in 2025 | Share of responses containing a domain | ChatGPT moved from ~60% to ~10% in six weeks | Presence in responses, not share of all citation links |
| Semrush Reddit URL study | 248K cited Reddit URLs across 217K prompts; refreshed October 2025 | Platform rank and response presence | #1 on Perplexity; 12.6% on SearchGPT; 9% on AI Mode | Reddit-only URL corpus and a separate Semrush methodology |
| SE Ranking stability study | 482 posts, 135 subreddits, six checks over three months; 2026 | Repeated citations per Reddit post | Stable posts averaged 83.4 citations vs. 1.6 for one-time posts | Measures persistence inside one monitored prompt cluster |
| Advanced Web Ranking | 40 queries; 201 citations in 12 expanded AI Overviews; July 2026 | Citation share in a small manual sample | 43 of 201 citations, about 21% | Directional sample, not a market-wide rate |
| Profound | ~680M citations; August 2024–June 2025 | Overall share and share within each engine's top 10 sources | 1.8%–6.6% overall; 11.3%–46.7% inside top-10-source subsets | Two denominators within the same dataset produce very different percentages |
Original audit result: the six outputs come from five research organizations, span samples from 40 queries to roughly 680 million citations, and produce no single directly comparable cross-engine "Reddit citation rate." The disagreement is not a reason to ignore the studies; it is evidence that the denominator and date belong beside every percentage.
If you want the fuller spread of citation-share numbers across engines beyond just Reddit, we pulled the wider picture together in our 2026 AI search statistics roundup.
The honest takeaway from these six research outputs is narrower: Reddit is a recurring source in several major AI answer engines, but its measured prominence depends on the vendor, engine, prompt set, date, unit, and denominator. None of these numbers should be repeated as "the" Reddit citation rate — they are six different snapshots of a moving target from five research organizations.
Why AI engines are built to favor forums right now
Money and access explain a lot of Reddit's specific advantage, but they don't explain why forum content in general has become more attractive to AI search products. Two things are driving that, independent of Reddit specifically.
The first is Google's own stated reasoning. Danny Sullivan's comment about people "craving authentic, experience-based information" wasn't only about Reddit — Google has said it's surfacing more content from smaller forums too, not just the big platforms (ppc.land). If you want the deeper mechanics of how models decide what to retrieve and cite in the first place, how LLMs actually work covers the retrieval side of this.
The second is a concrete product feature. On May 6, 2026, Google rolled out "Expert Advice" inside AI Overviews and AI Mode — a feature that surfaces quoted, first-hand posts from Reddit, forums, and blogs, with plans to show the original poster's name, handle, or community so users can judge the source before clicking through. Google's framing: "For many searches, people are increasingly seeking out advice from others" (TechCrunch). That's a deliberate product bet that first-person forum posts are more trustworthy signal than a polished article — exactly the kind of shift worth understanding if you're thinking about what AI visibility actually means for your own brand.
The practical content lesson is narrower than "post on Reddit": publish experience that can survive extraction. State the situation, the result, and the trade-off in one self-contained passage. A vague recommendation supplies no reusable evidence; a specific account of what worked, what failed, and for whom gives both readers and retrieval systems something they can evaluate.
Reddit's real 2024 traffic story
Away from AI citations specifically, Reddit had an enormous organic-search year in 2024, and this part is well-documented directly at the source. Sistrix's IndexWatch report, published January 17, 2025 and covering the 2024 calendar year in the US, found Reddit's Sistrix Visibility Index rose 190.85% over the year — from 667.79 to 1,942.29, a gain of 1,274.5 points. That made Reddit the third most-visible domain in Google's US search results by the end of 2024, up from roughly #92 at the start of 2023 (Sistrix).
I want to be precise about what that number actually is: a Visibility Index is a proprietary, weighted ranking metric — how prominently a domain shows up across tracked keywords — not a raw traffic count. You'll see much bigger, flashier percentages about Reddit's "traffic explosion" floating around online, sometimes in the thousands. I couldn't trace those back to a clean primary source in this research pass; they run through secondary SEO blogs, not through Sistrix or Google directly. The 190.85% Visibility Index figure is the one I can actually stand behind, cited to the firm that published it — use that one, and be skeptical of the rest.
The cracks in the story: does Reddit even want this?
Here's the part most coverage skips, and it's the most interesting piece of the whole picture: Reddit's own leadership isn't sold on AI Overviews being good for Reddit.
Start with a specific, verified data point from Sistrix: in UK Google results with AI Overviews, Reddit shows up as a normal organic search result in 49.4% of tracked queries — but is actually cited as an AI Overview source in only about 0.056% of cases (Sistrix). Sit with that gap for a second. Reddit's organic search visibility and its role as an AI-answer source are two almost entirely separate phenomena. Being "visible" and being "cited" are not the same thing, and conflating them is one of the most common mistakes in how people talk about AI search.
That gap lines up with what Reddit's own CEO has been saying publicly. In Reddit's Q2 2026 shareholder letter, around July 30, 2026, Steve Huffman pushed back directly on the value of AI Overviews to Reddit: "People don't want a summary of Reddit; they want Reddit," contrasting it unfavorably with how "10 blue links has driven tremendous value and growth" for the platform historically. He said Reddit would evaluate "every aspect" of its Google deal — including whether to end it — amid declining Reddit search-referral traffic (Engadget).
That's a genuinely uncomfortable position: Reddit is making real money licensing content to Google and OpenAI, while its own CEO publicly questions whether the arrangement is actually good for the business. It also fits reporting that Reddit is pushing for a new, dynamic, usage-based pricing structure in its next round of deals — where payments would scale up as Reddit content becomes more central to AI-generated answers, instead of a flat annual fee (Bloomberg, via CJR). If your engine's answer leans harder on Reddit, Reddit wants that reflected in the invoice. Rational, if you think the current flat fee undervalues what you're providing — but it also reads as real frustration bleeding through the strategy.
The misinformation problem nobody solved
Getting cited a lot isn't automatically a win, and Reddit's own content has caused two of the more embarrassing AI search failures on record.
The first is the glue-on-pizza episode. In May 2024, Google's AI Overviews went viral for telling some users to add non-toxic glue to pizza sauce to help the cheese stick — advice traced back to an 11-year-old joke comment on Reddit. It ran alongside other memorably bad answers, including one suggesting people eat "one small rock per day." Google subsequently said it would limit AI Overviews on nonsensical queries and filter out satirical or joke sources (MIT Technology Review).
The second is more serious and more recent. A Mount Sinai-led study published in The Lancet Digital Health on February 10, 2026 tested 20 large language models across more than a million prompts, including health myths sourced from Reddit posts — things like false claims that Tylenol causes autism, or that rectal garlic boosts immunity. Across all the prompts tested, models fell for fabricated medical claims about 32% of the time. Worth being precise here: the reporting on this study doesn't isolate a distinct error rate specific to Reddit-sourced claims alone — the 32% figure covers fabricated medical claims broadly, of which Reddit-sourced myths were one input, not the whole test set (Euronews, reporting on The Lancet Digital Health).
Neither of these means "Reddit is unreliable" as a blanket statement — most cited Reddit threads are ordinary Q&A exchanges, and the Semrush data above suggests low-upvote, low-drama threads are what actually gets cited most, not viral joke comments. But it's a real cost of leaning on first-person, unedited, unverified forum content at scale: some fraction of what gets surfaced with total confidence is a joke, or wrong, or both.
The legal fight behind the citations
Everything above assumes AI companies are citing Reddit content they have a right to use. Two lawsuits argue that's not true for everyone.
Reddit sued Anthropic in California state court on June 4, 2025, alleging Anthropic scraped and commercially used "millions, if not billions" of Reddit posts and comments without a license — explicitly contrasting Anthropic's approach with Google and OpenAI, which paid for access. A judge later allowed most of Reddit's claims to proceed (TechCrunch / Law360 / National Law Review).
Then, on October 22, 2025, Reddit sued Perplexity along with three scraping-adjacent companies — Oxylabs, AWMProxy, and SerpApi — in the Southern District of New York, alleging "industrial-scale scraping" of Reddit comments that bypassed anti-scraping protections, and seeking a DMCA-based injunction. Perplexity's response was that it doesn't train models on Reddit content at all, only summarizes and cites public discussions it finds (Romano Law / Built In).
Line these two lawsuits up against the licensing deals and the whole picture snaps into focus: Reddit's actual position is "cite us all you want, but pay first." The companies that paid — Google, OpenAI — get official access, a seat at the table, and increasingly generous product placement like the Expert Advice feature. The companies that didn't pay are in court. It's less a story about which AI engines "believe" Reddit is authoritative and more a story about which ones signed a check.
What this actually means if you're trying to get cited
None of this is Reddit-specific advice for your own brand — you can't license your way into becoming the next Reddit. But the underlying pattern is worth taking seriously: AI engines are visibly rewarding first-person, unpolished, community-sourced answers over content that reads like it was written to rank. If your brand's presence on Q&A platforms, review threads, and communities is thin, you're competing for citations against a format that's currently winning by design, not by accident. That's a big part of why AI engines keep skipping past well-optimized brand pages in favor of a five-upvote comment thread — see why ChatGPT doesn't recommend your brand if that's happened to you. It also connects to the broader shift where fewer people click through to any website at all — see zero-click SEO for GEO for that angle.
This is exactly the kind of pattern FixAEO is built to catch: it tracks how often your brand actually gets cited across ChatGPT, Claude, Gemini, Perplexity, Grok, DeepSeek, Copilot, and Google AI Overviews, and which domains — Reddit included — are winning the citations you're not getting. If you want the tactical playbook for earning Reddit citations rather than just understanding why they happen, I wrote a separate piece on that: the Reddit AI citations playbook.
What would change this conclusion
ARES is a testable explanation, not a permanent law. I would revise the conclusion if any of these signals changed materially: Google or OpenAI lost structured Reddit access; Reddit's live crawler rules or API terms removed broad retrieval routes; repeated prompt tracking showed Reddit disappearing across multiple engines for at least three consecutive checks; or stable first-person threads stopped outperforming one-time mentions in a comparable longitudinal study. Those triggers distinguish a genuine structural shift from one vendor's weekly ranking change.
Research notes, disclosure, and revision record
Method. On September 23, 2026, I reviewed six published research outputs from Ahrefs, Semrush, SE Ranking, Advanced Web Ranking, and Profound. For each, I extracted the sample size, observation window, engine, unit of analysis, denominator, and Reddit-specific result before comparing the findings. I separately checked the current Reddit robots.txt, official or filing-backed data-access announcements, litigation reporting, and source dates.
Disclosure and limitations. There are no affiliate links or sponsored placements in this article. I founded FixAEO, which is mentioned as the product context behind this investigation. The normalized table is original FixAEO analysis of published studies, not a new 680-million-citation dataset of our own. Several source datasets are proprietary, so the audit can compare disclosed methodology but cannot independently reproduce every vendor's underlying prompt set.
Fact-check and revision status. Researched, written, and fact-checked by Nitish Kumar Yadav against the linked sources. The September 23, 2026 revision added current crawler-policy context, primary Profound data, the ARES model, a six-study source audit, explicit falsification triggers, Dataset markup, and visible evidence limitations. Review again by December 23, 2026, or sooner after a data-deal, crawler-policy, court, or material citation-trend change. Corrections follow the FixAEO editorial policy.
TL;DR
Reddit's prominence in AI search isn't organic luck — Google pays roughly $60M a year and OpenAI has its own undisclosed deal for structured Data API access. A 2024 crawler crackdown strengthened Reddit's control, but the live 2026 robots.txt is no longer a simple "Google only" blocklist. Citation-share studies from Ahrefs, Semrush, SE Ranking, Advanced Web Ranking, and Profound use different samples and denominators and often contradict each other; Semrush's own tracking showed Reddit's ChatGPT citation frequency swinging from about 60% to about 10% in six weeks. Treat every "Reddit is cited X% of the time" claim as a dated snapshot, not a constant.
FAQ
Does Google really pay Reddit for its content?
Yes. Reuters first reported in February 2024 that Google agreed to pay Reddit roughly $60 million a year to license Reddit's content for AI training and search (MediaPost). Reddit's IPO filing separately disclosed $203 million in aggregate data-licensing contract value.
Does OpenAI pay Reddit too?
OpenAI and Reddit announced a data-licensing and advertising partnership on May 16, 2024, giving OpenAI access to Reddit's Data API (TechCrunch). Neither company has disclosed the price. Search Engine Land's widely-cited ~$70 million estimate is their own calculation, not a confirmed figure.
Why can't other search engines show Reddit results anymore?
In July 2024, Reddit changed its robots.txt and major non-Google search crawlers temporarily lost access. The live 2026 file is different: it broadly allows the site while restricting specific endpoints and formats. Access now depends on more than robots.txt, including Reddit's API terms, commercial licenses, and technical enforcement (current robots.txt).
How often do AI engines actually cite Reddit?
It depends entirely on which study you read and when it was run. Ahrefs found Reddit outside ChatGPT's and Perplexity's top 10 domains in June 2025, while a separate Semrush study from around the same period ranked Reddit #1 on Perplexity. Semrush's own 13-week tracker also found Reddit's ChatGPT citation share collapse from about 60% to about 10% in six weeks. There is no single stable "Reddit citation rate" — it moves by platform, by week, and by who's measuring it.
Is Reddit's search visibility the same as its AI citation rate?
No, and the gap is bigger than most people assume. Sistrix found that in UK AI Overviews, Reddit appears as a normal organic result in 49.4% of tracked queries but is only actually cited as an AI Overview source in about 0.056% of cases (Sistrix). Showing up in search and getting cited by the AI summary are largely separate outcomes.
Is Reddit happy with how AI Overviews use its content?
Not entirely. In Reddit's Q2 2026 shareholder letter, CEO Steve Huffman said "people don't want a summary of Reddit; they want Reddit," and said Reddit would evaluate every part of its Google relationship, including whether to keep it, as Reddit's own search-referral traffic has declined (Engadget).
Is Reddit suing any AI companies?
Yes, two. Reddit sued Anthropic in June 2025 over alleged unlicensed scraping of Reddit content, and a judge let most of the claims proceed. Reddit sued Perplexity and three scraping-adjacent companies in October 2025 over alleged "industrial-scale scraping" that bypassed its anti-scraping protections (National Law Review, Romano Law).
Can Reddit misinformation end up in AI answers?
Yes — it already has. Google's AI Overviews told some users to add glue to pizza sauce in 2024, advice traced back to a joke Reddit comment (MIT Technology Review). A February 2026 Lancet Digital Health study also found LLMs fell for fabricated medical claims, some sourced from Reddit health myths, about 32% of the time across the full test set (Euronews).
Related reading
How LLMs Actually Work — and Why It Decides Whether AI Recommends Your Brand
How does ChatGPT decide what to say about your brand? A plain-English guide to next-token prediction, retrieval, and why answers change every time.
26 min readWhat Is AI Visibility (and Why It Matters in 2026)
AI visibility measures whether ChatGPT, Gemini, and other AI engines mention, recommend, or cite your brand — and why tracking it matters in 2026.
14 min readAI Search Statistics 2026: How AI Replaces Google
20+ verified, source-linked AI search statistics for 2026 — who uses AI vs Google, how fast it's growing, and the viral stats that don't hold up.
16 min read7 Zero-Click SEO Tips for Better GEO Visibility
Zero-click search now swallows most Google queries. Seven evidence-backed GEO tactics, with sources, to get cited in AI answers instead of chasing clicks.
15 min readWhy ChatGPT doesn't recommend your brand
ChatGPT SEO fix: six reasons ChatGPT names competitors instead of you, ranked by frequency across 1,000+ FixAEO scans — with a fix for each and a 30/60/90 day plan.
17 min readHow to get cited via Reddit: the 2026 AI search playbook
Learn how to earn Reddit citations in ChatGPT, Perplexity, and Google AI search without spam, using a sourced 90-day playbook for brands.
24 min read
Free AEO tools
Put this into practice with free FixAEO tools — no signup required.
AI Visibility Checker
Score your brand across 9 AI engines
AEO Audit Tool
Answer-engine readiness scan
Schema Generator
Build valid JSON-LD structured data
llms.txt Generator
Create a spec-compliant llms.txt
Sitemap Validator
Check your XML sitemap for errors
AI Content Grader
Grade content for AI citation readiness